CLI Reference#
On this page: Commands · Flags · Example · Licensing · Validating Config · Validating a License · Retries · Error Output · Connection Pool · Warmup · Request Timeout · Safety Caps · Run Behaviour · Formatting · Performance Testing
Commands#
| Command | Description |
|---|---|
up | Create schema (tables, indexes) |
seed | Populate tables with initial data |
run | Execute the benchmark workload |
deseed | Delete seeded data (truncate tables) |
down | Tear down schema (drop tables) |
all | Run up, seed, run, and down in sequence |
capture | Generate a workload config from real query statistics |
cluster coordinator | Start the cluster coordinator server |
cluster agent | Start a cluster agent |
cluster submit | Submit a workload to the cluster |
cluster status [id] | Show status of one or all cluster jobs |
cluster stream <id> | Stream live progress from a running cluster job |
cluster cancel <id> | Cancel a running cluster job |
cluster agents | List active cluster agents |
cluster reset | Reset coordination database tables |
compare all | Run up, seed, run, deseed, and down on both databases |
compare up | Create schema on both databases |
compare seed | Populate tables on both databases |
compare run | Run workload on both databases simultaneously |
compare deseed | Delete seeded data on both databases (truncate tables) |
compare down | Tear down schema on both databases |
doctor | Opinionated analysis that flags correct but potentially problematic .edg config elements |
edg <expression> | Evaluate a single expression and print the result |
fmt | Format .edg config files |
functions [search] | List available expression functions, optionally filtered by name |
fuzz <expression> | Evaluate an expression many times and report output statistics |
init | Generate a starter config from an existing database schema |
jobs serve | Start an HTTP server that accepts workload configs via API |
jobs stream [id...] | Stream live progress from one or more running jobs (--all for every running job) |
jobs submit | Submit a workload config to the job server |
perf breakpoint | Ramp workers until performance degrades |
repl | Interactive expression evaluator with tab completion |
scaffold | Interactive config generator wizard |
signal | Draw a signal curve in the terminal and export it as edg |
signals [search] | List the load shapes edg ships with, optionally filtered by name or description |
stage | Generate data to files instead of a database |
sync down | Tear down schema on both databases |
sync run | Write identical data to multiple databases |
sync verify | Verify data consistency between two databases |
template | Print a template workload config to stdout |
validate config | Validate a config file without connecting to a database |
validate license | Validate a license key and print its details |
version | Print the version |
workload <name> <command> | Run a built-in workload without a config file |
Running edg with an expression (no subcommand) evaluates it and prints the result. Bare words are treated as gofakeit patterns, so edg email is equivalent to edg "gen('email')". For expressions with parentheses or special characters, quote the argument.
A typical workflow runs the commands in order: up -> seed -> run -> down. The all command runs this entire sequence in a single invocation.
Flags#
Flags are grouped by scope. Global flags work anywhere and may be given before or after the subcommand; every other flag belongs to the commands listed with its group and must come after the subcommand:
edg run --url ... --config ...   # correct
edg --url ... run --config ...   # unknown flag: --url
Run edg <command> --help to see exactly which flags a command accepts.
Global Flags#
Accepted by every command.
| Flag / Env Var | Short | Default | Description |
|---|---|---|---|
--configEDG_CONFIG | Path or URL to the workload config file (required for database commands, optional for repl) | ||
--driverEDG_DRIVER | pgx | Database driver name (pgx, mysql, mongodb, cassandra, sqlite, redis, mssql, oracle, dsql, spanner, or test) | |
--licenseEDG_LICENSE | License key for pro drivers (see Licensing) | ||
--rng-seedEDG_RNG_SEED | PRNG seed for deterministic output (useful for regression testing) | ||
--no-colorEDG_NO_COLOR | false | Disable colored log output. The standard NO_COLOR=1 environment variable is also respected per the no-color convention. | |
--sim-periodEDG_SIM_PERIOD | Override the period of the config’s sim block (e.g. 24h). Ignored when the config declares no sim block. | ||
--sim-inEDG_SIM_IN | Override the in of the config’s sim block (e.g. 5m), i.e. the wall-clock time the period compresses into. Ignored when the config declares no sim block. | ||
--csv-file | CSV file to load as a reference table. The filename (minus extension) becomes the dataset name. Repeatable. See Configuration > Reference for details. | ||
--csv-directory | Directory of CSV files to load as reference tables. Each .csv file becomes a dataset. Non-recursive. Repeatable. | ||
--plugin | Path to a plugin .so or .wasm file. Repeatable. | ||
--embed-api-keyEDG_EMBED_API_KEY | API key for the embedding provider. Required for embed() expressions. | ||
--embed-urlEDG_EMBED_URL | Embedding API URL. Any OpenAI-compatible endpoint works (Ollama, vLLM, Azure OpenAI, etc.). | ||
--embed-modelEDG_EMBED_MODEL | Embedding model name sent in the API request. | ||
--embed-dimensionsEDG_EMBED_DIMENSIONS | 1536 | Number of dimensions requested from the embedding model. Must match the VECTOR(n) column type. | |
--embed-max-batchEDG_EMBED_MAX_BATCH | 0 | Max texts per embedding API call in batch queries. 0 means unlimited (all texts in one call). E.g. 30 on a 100-row batch produces 4 API calls (30, 30, 30, 10). | |
--complete-api-keyEDG_COMPLETE_API_KEY | API key for the LLM provider. Required for complete() expressions. | ||
--complete-urlEDG_COMPLETE_URL | LLM API URL. Any OpenAI-compatible endpoint works. | ||
--complete-modelEDG_COMPLETE_MODEL | LLM model name sent in the API request. |
Connection Flags#
Accepted by up, seed, deseed, down, run, all, workload, perf, and jobs. compare, sync, and cluster take everything below except --url, which their own --a-url/--source-url/--target-url flags replace. init and capture take --url only.
| Flag / Env Var | Short | Default | Description |
|---|---|---|---|
--urlEDG_URL | Database connection URL. For Cassandra, comma-separated hosts are supported in the host portion (e.g. cassandra://user:pass@host1,host2,host3:9042/keyspace). Port, auth, and keyspace are parsed from the URL; the port applies to all hosts. For SQLite it’s a file path or file: URI, passed to the driver unchanged so pragmas can be set (e.g. file:edg.db?_pragma=busy_timeout(5000)). For Redis a bare host:port is accepted and prefixed with redis://. | ||
--targetEDG_TARGET | Name of the config target to act on. An error against a config that declares none, which uses --url instead. Defaults to the first declared target. On run, naming a target narrows a multi-target config down to that one database instead of driving them all. | ||
--pool-sizeEDG_POOL_SIZE | 0 | Maximum number of open database connections. 0 sizes the pool to --workers, or to the busiest stage’s worker count when the config declares stages, so each worker gets its own connection. | |
--max-conn-lifetimeEDG_MAX_CONN_LIFETIME | 30m | Maximum age of a database connection before it’s recycled. 0 means connections are never recycled. Ignored by MongoDB and Cassandra. See Connection Pool for details. | |
--max-conn-lifetime-jitterEDG_MAX_CONN_LIFETIME_JITTER | 5m | Random duration added to --max-conn-lifetime per connection so they don’t all recycle at once. Only supported by the pgx and dsql drivers. | |
--cassandra-default-consistencyEDG_CASSANDRA_DEFAULT_CONSISTENCY | Default consistency level for Cassandra queries. Accepts: any, one, two, three, quorum, all, local_quorum, each_quorum, local_one. When unset, the driver default (quorum) is used. | ||
--cassandra-idempotentEDG_CASSANDRA_IDEMPOTENT | false | Mark all Cassandra queries as idempotent. Enables speculative execution and retry on other nodes when a query fails mid-flight. Safe for read-heavy or repeatable-write workloads. | |
--cassandra-no-discoveryEDG_CASSANDRA_NO_DISCOVERY | false | Skip initial host discovery for Cassandra. Prevents the driver from querying system.peers to find other nodes, connecting only to the seed host in --url. Speeds up connection startup. | |
--cassandra-serial-consistencyEDG_CASSANDRA_SERIAL_CONSISTENCY | Serial consistency level for Cassandra lightweight transactions (LWT). Accepts: serial (global Paxos across all DCs) or local_serial (Paxos within local DC only). When unset, the driver default (local_serial) is used. Use serial for multi-DC consistency testing. |
Workload Flags#
Accepted by the commands that drive workers: run, all, workload, perf, jobs, cluster, and compare.
| Flag / Env Var | Short | Default | Description |
|---|---|---|---|
--retriesEDG_RETRIES | 0 | Number of transaction retry attempts on error. Uses exponential backoff (1ms, 2ms, 4ms, …). Only applies to transactions, not standalone queries. See Retries for details. | |
--errorsEDG_ERRORS | false | Print worker errors to stderr. See Error Output for details. | |
--no-waitEDG_NO_WAIT | false | Ignore wait durations configured in workload queries | |
--no-atomic-txEDG_NO_ATOMIC_TX | false | Skip BEGIN/COMMIT for transaction blocks. Queries still run sequentially with shared locals and ref_same, but each statement commits independently. rollback_if conditions are skipped. | |
--drain-timeoutEDG_DRAIN_TIMEOUT | 5s | Max time for in-flight operations to complete at shutdown. When the run timer fires, workers finish their current iteration using a separate context with this deadline instead of being cancelled immediately. Prevents silent result drops that cause expectation mismatches. | |
--request-timeoutEDG_REQUEST_TIMEOUT | 0 | Default timeout per query execution. 0 means no timeout. Overridden by per-query request_timeout when set. See Request Timeout for details. | |
--metrics-addrEDG_METRICS_ADDR | Address for Prometheus metrics endpoint (e.g. :9090). See Observability for details. | ||
--metrics-samplesEDG_METRICS_SAMPLES | 10000 | Maximum latency samples kept in memory for percentile calculation. Uses a sliding window (ring buffer) so memory stays bounded during long runs. Only affects p90/p95/p99; count, and QPS are always exact. | |
--overwriteEDG_OVERWRITE_STATS | false | Overwrite printed stats in-place instead of appending new blocks. Each progress tick clears the previous output and reprints, keeping the terminal clean during long runs. | |
--tuiEDG_TUI | false | Launch the interactive TUI for workload stats. See TUI for details. | |
--x-axisEDG_X_AXIS | start | TUI graph x-axis mode: clock (wall clock) or start (elapsed from 00:00:00) |
Per-Command Flags#
Registered on the individual commands that support them.
| Flag / Env Var | Short | Default | Description |
|---|---|---|---|
--duration | -d | 1m | Benchmark duration (run and all commands) |
--workers | -w | 1 | Number of concurrent workers. For run and all: number of worker goroutines. For seed: number of concurrent insert workers per exec_batch query. |
--print-interval | 1s | Progress reporting interval (run and all commands) | |
--warmup-duration | 0 | Warmup period before collecting metrics (e.g. 10s). Workers run during warmup but results are discarded. See Warmup for details. | |
--max-rowsEDG_MAX_ROWS | 0 | Maximum total rows to insert across all seed queries. 0 means unlimited. Accepts suffixed values: K (×1,000), M (×1,000,000), B (×1,000,000,000). Applies to seed and all commands. See Safety Caps for details. | |
--max-durationEDG_MAX_DURATION | 0 | Maximum wall-clock time for the command. 0 means unlimited. On seed, caps the seed phase. On run, caps the run across all stages. On all, caps the entire lifecycle (up through down). See Safety Caps for details. | |
--max-queriesEDG_MAX_QUERIES | 0 | Maximum total query executions during the run phase. 0 means unlimited. Accepts suffixed values: K (×1,000), M (×1,000,000), B (×1,000,000,000). Applies to run and all commands. See Safety Caps for details. | |
--max-qpsEDG_MAX_QPS | 0 | Maximum total queries per second. 0 means unlimited. Accepts suffixed values: K (×1,000), M (×1,000,000), B (×1,000,000,000). Applies to run and all commands. See Safety Caps for details. | |
--pause | false | Wait for input after the run finishes, before deseed and down. Press enter or ctrl+c to carry on. Applies to all and compare all. See Pausing before teardown for details. | |
--env | -e | Set an environment variable for env()/env_nil(), as KEY=VALUE. Repeatable, so a value containing a comma survives intact. Shadows the OS environment for expression evaluation only. Accepted by up, seed, deseed, down, run, all, sync, jobs submit and cluster submit. See Per-run environment for details. | |
--env-file | Read environment variables for env()/env_nil() from a KEY=VALUE file. An explicit --env wins over the file. See Per-run environment for details. |
Per-run environment#
env('NAME') and env_nil('NAME') resolve against the --env / --env-file
values first and the OS environment second, so the same config file can be
shaped per invocation without exporting anything:
edg run --config workload.edg --url "$URL" -e SHAPE_AMP=0.9

# equivalent, since job env falls back to the OS environment
SHAPE_AMP=0.9 edg run --config workload.edg --url "$URL"
SHAPE_AMP is not a name edg knows - the names are whatever workload.edg
reads with env_nil(), and it decides what they mean. See
Shapes for the config the
SHAPE_* examples on this page drive.
An override set to the empty string is a hit, not a miss: -e OPTIONAL=
makes env_nil('OPTIONAL') return "" rather than nil.
--env-file is a deliberately dumb KEY=VALUE per line format. # comments
and blank lines are skipped, and a value is the rest of the line verbatim -
no quote stripping, no escape sequences, no variable expansion. Anything
richer belongs in the shell.
# peak.env
SHAPE_PEAK_HOUR=3
SHAPE_AMP=0.9
The same flags travel with a submission to a job server or a cluster, where they matter more: there, the process evaluating the config is a server or agent whose own environment is fixed at deploy time.
Use this for parameters, not secrets. On a cluster, job env is stored in the coordination database in plaintext.
Cassandra LWT / CAS workloads require
--no-atomic-tx. Cassandra does not support lightweight transactions (IFconditions) inside batches, so transaction blocks must run each statement independently. For multi-DC consistency testing, set--cassandra-serial-consistency serialto use global Paxos consensus. A typical LWT consistency test invocation looks like:edg run \ --driver cassandra \ --url "cassandra://user:pass@host1,host2,host3:9042/keyspace" \ --cassandra-default-consistency local_quorum \ --cassandra-serial-consistency serial \ --no-atomic-tx \ -w 10 -d 5m
MongoDB tuning is done via URI parameters in
--urlrather than dedicated flags. The MongoDB driver parses all options from the connection string, so append query parameters to control consistency, read routing, and connection behaviour. Common parameters:
Parameter Values Effect w0,1,2, …,majority, or a custom tag set nameWrite concern. See write concern values below. readConcernLevellocal,available,majority,linearizable,snapshotRead isolation level. See read concern values below. readPreferenceprimary,primaryPreferred,secondary,secondaryPreferred,nearestWhich replica serves reads. nearestgives lowest latency;secondaryoffloads the primary.retryWritestrue,falseRetry failed writes once (default: true).directConnectiontrue,falseConnect to a single node without topology discovery. loadBalancedtrue,falseRequired when connecting through an L4 load balancer (e.g. Atlas Serverless). connectTimeoutMSmilliseconds Connection timeout (edg default: 10000).serverSelectionTimeoutMSmilliseconds How long the driver waits for a suitable server (edg default: 10000).Example with majority write concern and linearizable reads:
edg run \
  --driver mongodb \
  --url "mongodb://localhost:27017/mydb?w=majority&readConcernLevel=linearizable" \
  --config workload.edg \
  -w 10 -d 5m
MongoDB write concern values#
wvalueMeaning 0Fire-and-forget. No acknowledgement from the server. 1Acknowledged by primary only (default). 2,3, …Acknowledged by that many replica set members. majorityAcknowledged by a majority of replica set members. Won’t be rolled back. custom tag Acknowledged by members matching a custom getLastErrorModestag set.MongoDB read concern values#
readConcernLevelvalueMeaning localMost recent data from the node (default for primary reads). May be rolled back. availableLike localbut for sharded clusters. It doesn’t wait for orphaned docs to be cleaned. Lowest latency.majorityOnly data acknowledged by a majority. Won’t be rolled back. linearizableReflects all successful majority writes before the read. Single-document only, primary only. Highest consistency. snapshotPoint-in-time snapshot across a transaction. Requires w=majority. Transactions only.For consistency testing,
w=majority+readConcernLevel=majorityis the common combination.snapshotis stronger but only works inside transactions. Use--retries 3to handle transientWriteConflicterrors under contention.
Every flag with an env var listed above can be set via the environment instead of the command line. Flags take precedence over environment variables, which take precedence over defaults.
export EDG_URL="postgres://root@localhost:26257?sslmode=disable"
export EDG_DRIVER="pgx"
export EDG_CONFIG="workload.edg"

# No need to pass --url, --driver, or --config:
edg run -w 10 -d 5m

# Flags override env vars when both are set:
edg run -w 10 -d 5m --driver mysql --url "user:pass@tcp(localhost:3306)/db"
Remote Config#
The --config flag accepts HTTP and HTTPS URLs. edg fetches the config and runs it the same as a local file.
# Serve a config directory
python3 -m http.server 8000 -d examples/tpcc

# Run edg against it
edg all \
--driver pgx \
--config "http://localhost:8000/workload.edg" \
--url "postgres://root@localhost:26257?sslmode=disable" \
-w 1 \
-d 10s
!includedirectives are not resolved for remote configs, since there is no local filesystem to resolve relative paths against.
Example#
Database#
Run each lifecycle command individually against a database, or use all to run the entire sequence in one invocation.
edg up \
--driver pgx \
--config examples/tpcc/crdb.edg \
--url "postgres://root@localhost:26257?sslmode=disable"

edg seed \
--driver pgx \
--config examples/tpcc/crdb.edg \
--url "postgres://root@localhost:26257?sslmode=disable"

edg run \
--driver pgx \
--config examples/tpcc/crdb.edg \
--url "postgres://root@localhost:26257?sslmode=disable" \
-w 100 \
-d 1m

edg deseed \
--driver pgx \
--config examples/tpcc/crdb.edg \
--url "postgres://root@localhost:26257?sslmode=disable"

edg down \
--driver pgx \
--config examples/tpcc/crdb.edg \
--url "postgres://root@localhost:26257?sslmode=disable"
Or use all to run the entire workflow in one command:
edg all \
--driver pgx \
--config examples/tpcc/crdb.edg \
--url "postgres://root@localhost:26257?sslmode=disable" \
-w 100 \
-d 5m
Aurora DSQL#
The dsql driver uses AWS IAM authentication instead of a username and password. Pass the cluster endpoint as the --url value:
edg all \
--driver dsql \
--config workload.edg \
--url "clusterid.dsql.us-east-1.on.aws" \
-w 10 \
-d 5m
AWS credentials are resolved from the standard chain (environment variables, ~/.aws/credentials, IAM role, etc.). The region is parsed from the cluster endpoint automatically. Auth tokens are refreshed on every new connection, so long-running workloads work without interruption.
DSQL uses PostgreSQL-compatible SQL, so use $1, $2 placeholders in your queries.
Licensing#
The pgx, mysql, mongodb, cassandra, sqlite, and redis drivers are free to use. Pro drivers (oracle, mssql, dsql, spanner) require a license key passed via --license or EDG_LICENSE. The license is validated before connecting to the database. See the Licensing page for full details.
Validating Config#
The validate config command parses a config file and checks it for errors without connecting to a database. It catches syntax errors, invalid expressions, unknown function calls, unknown gofakeit patterns passed to gen(), gen_batch(), json_arr() and array(), duplicate query names, shadowed built-ins, and invalid query types. Errors include line numbers when available.
edg validate config --config examples/tpcc/workload.edgconfig is validAdd --explain for enhanced error messages with explanations and correct syntax examples:
edg validate config --config workload.edg --explainline 42: duplicate query name "seed_users"
Query names must be unique across all sections. They serve as dataset keys
for ref_* functions and as metric labels. Rename one of the duplicates.This is useful for catching mistakes before deploying a workload or as a CI check.
Validating a License#
The validate license command checks whether a license key is valid for a given driver and prints the license details.
edg validate license --driver oracle --license "your-license-key"License info:
ID: acme-corp
Email: admin@acme.com
Drivers: [oracle mssql]
Issued at: 2025-01-15
Expires at: 2026-01-15
License is valid for driver "oracle".If the driver doesn’t require a license, the output tells you:
edg validate license --driver pgx --license "your-license-key"License info:
ID: acme-corp
Email: admin@acme.com
Drivers: [oracle mssql]
Issued at: 2025-01-15
Expires at: 2026-01-15
Driver "pgx" does not require a license.If the license is expired or doesn’t cover the requested driver, you’ll see an error:
edg validate license --driver dsql --license "your-license-key"License info:
ID: acme-corp
Email: admin@acme.com
Drivers: [oracle mssql]
Issued at: 2025-01-15
Expires at: 2026-01-15
Error: license does not include driver "dsql" (licensed: [oracle mssql])The EDG_LICENSE environment variable is also accepted:
export EDG_LICENSE="your-license-key"
edg validate license --driver oracleRetries#
The --retries flag controls how many times a failed transaction is retried before the error is recorded. The default is 0 (no retries). Retries only apply to transactions (queries wrapped in a transaction: block), not standalone queries.
When a transaction fails, edg waits with exponential backoff before retrying:
| Attempt | Backoff |
|---|---|
| 1st retry | 2ms |
| 2nd retry | 4ms |
| 3rd retry | 8ms |
| 4th retry | 16ms |
| nth retry | 2^n ms |
If all retry attempts fail, the last error is recorded in the stats and the worker continues to the next iteration. Context cancellation (e.g. Ctrl+C or duration expiry) stops retries immediately.
edg run \
  --driver pgx \
  --config workload.edg \
  --url ${DATABASE_URL} \
  --retries 3 \
  -w 10 \
  -d 5m
Error Output#
By default, individual query errors during the run phase are counted but not printed. The --errors flag prints each error to stderr as it occurs, which is useful for debugging:
edg run \
  --driver pgx \
  --config workload.edg \
  --url ${DATABASE_URL} \
  --errors \
  -w 10 \
  -d 5m
2025/04/23 14:32:07 ERROR run error worker=3 error="running run query debit_source: pq: insufficient funds"
2025/04/23 14:32:07 ERROR run error worker=7 error="running run query debit_source: pq: insufficient funds"Without --errors, the same failures still appear in the summary table’s ERRORS column and count toward error_rate in expectations.
Connection Pool#
Three flags tune the connection pool: --pool-size, --max-conn-lifetime, and --max-conn-lifetime-jitter.
Pool size#
The --pool-size flag sets the maximum number of open database connections. Left at the default 0, the pool is sized to the command’s --workers value so each worker gets its own connection.
A staged run takes its concurrency from the stages rather than from --workers, so the pool follows the busiest stage instead. A config whose peak stage declares 16 workers gets a pool of 16 even though --workers is left at its default of 1.
Setting pool size explicitly is useful for:
- Simulating constrained environments where the application has a fixed connection budget.
- Preventing connection exhaustion when running with many workers against a database with connection limits.
- Isolating connection overhead from query performance in benchmarks.
The value is used verbatim. With a staged config, if the busiest stage asks for more workers than the pool has connections, edg logs a warning and the workers contend.
Connection lifetime#
The --max-conn-lifetime flag caps how long a connection lives before it’s closed and replaced, defaulting to 30m. Recycling connections exercises reconnect paths and lets a client rebalance across cluster nodes after a topology change. Set it to 0 to keep connections for the whole run.
--max-conn-lifetime-jitter (default 5m) adds a random duration of up to that length to each connection’s lifetime, so a pool opened at the same moment doesn’t recycle in lockstep.
Driver support#
| Driver | Pool size | Connection lifetime | Jitter |
|---|---|---|---|
pgx, dsql | ☑️ | ☑️ | ☑️ |
mysql, mssql, oracle, spanner, sqlite | ☑️ | ☑️ | |
redis | ☑️ | ☑️ | |
mongodb | ☑️ | ||
cassandra | ☑️ (divided across hosts) |
Unsupported settings are ignored rather than rejected, so the same flags work across drivers.
edg run \
  --driver pgx \
  --config workload.edg \
  --url ${DATABASE_URL} \
  --pool-size 20 \
  -w 50 \
  -d 5m
In this example, 50 workers share 20 connections. Workers that can’t acquire a connection will block until one becomes available.
Warmup#
The --warmup-duration flag runs workers for a specified period before collecting metrics. During warmup, query results are discarded. They don’t appear in progress output, the summary, Prometheus metrics, or expectations.
This produces cleaner benchmark results by allowing the database to warm its caches, JIT-compile query plans, and reach a steady state before measurement begins.
edg run \
  --driver pgx \
  --config workload.edg \
  --url ${DATABASE_URL} \
  --warmup-duration 30s \
  -w 10 \
  -d 5m
In this example, workers run for 30 seconds of warmup (discarded), then 5 minutes of measured execution. The total wall-clock time is 5m30s.
When using stages, warmup applies before the first stage begins collecting metrics.
Request Timeout#
The --request-timeout flag sets a default timeout for each individual query execution. When set, every query gets a context deadline of the specified duration. A query that exceeds the timeout is cancelled and counted as an error.
Per-query timeouts can be set with request_timeout in the config, which takes precedence over the global flag:
run {
  fast_lookup(request_timeout: 500ms) `SELECT * FROM users WHERE id = $1` (ref('fetch_users').id)
  slow_report(request_timeout: 30s) `SELECT count(*) FROM orders GROUP BY region`
}
When neither a per-query request_timeout nor the global --request-timeout flag is set, queries run without a timeout (bounded only by the worker’s context).
Safety Caps#
The --max-rows, --max-duration, and --max-queries flags set hard ceilings on work performed, preventing runaway workloads from consuming unbounded resources.
Numbers can be provided in the following formats:
| Value | Resolves to |
|---|---|
| 40000 | 40000 1 |
| 100K / 100k | 100000 |
| 25M / 25m | 25000000 |
| 17B / 17b | 17000000000 |
--max-rows#
Limits the total number of rows inserted during seeding. A batch query that would cross the cap generates only the rows still owing, and the remaining seed queries are skipped; seeding then completes normally. The cap is exact, so --max-rows 100000 against a config seeding 20,000 merchants and 500,000 cards inserts every merchant and 80,000 cards.
Available on: seed, all
edg seed \
  --driver pgx \
  --config workload.edg \
  --url ${DATABASE_URL} \
--max-rows 500K--max-duration#
Sets a wall-clock timeout on the command. When time expires, the context is cancelled and work stops gracefully.
- On
seed: caps the seed phase - On
run: caps the entire run, including all stages - On
all: caps the full lifecycle (up, seed, run, deseed, down)
This is independent of --duration, which sets the benchmark measurement period for the run phase. Use --max-duration as an outer safety net.
edg all \
  --driver pgx \
  --config workload.edg \
  --url ${DATABASE_URL} \
  -w 10 \
  -d 1h \
--max-duration 30m--max-queries#
Limits the total number of query executions during the run phase. Workers check the counter after each iteration and stop when the cap is reached. The count is shared across all workers.
Available on: run, all
edg run \
  --driver pgx \
  --config workload.edg \
  --url ${DATABASE_URL} \
  -w 10 \
  -d 1h \
--max-queries 1M--max-qps#
Limits the total number of queries per second during the run phase. The rate is shared across all workers, guaranteeing a ceiling to QPS regardless of worker count.
It’s a ceiling, not a target: when a stage declares its own lower qps, the stage rate still applies, and a stage asking for more than --max-qps is held at the cap.
Available on: run, all
edg run \
  --driver pgx \
  --config workload.edg \
  --url ${DATABASE_URL} \
  -w 10 \
  -d 1h \
  --max-qps 1K
Command availability#
| Flag | seed | run | all |
|---|---|---|---|
--max-rows | Yes | - | Yes (seed phase) |
--max-duration | Yes | Yes | Yes (entire lifecycle) |
--max-queries | - | Yes | Yes (run phase) |
--max-qps | - | Yes | Yes (run phase) |
Environment variables#
All three flags can be set via environment variables:
export EDG_MAX_ROWS=1M
export EDG_MAX_DURATION=30m
export EDG_MAX_QUERIES=500K
Flags take precedence over environment variables.
Run Behaviour#
Workers and Initialisation#
Each worker gets its own isolated environment. The init section runs once, and its results are cloned to each worker so that functions like ref_rand and ref_diff don’t interfere across workers. Per-worker state includes sequence counters (seq), permanent row picks (ref_perm), and NURand constants.
Stages#
When a config file includes a stages section, each stage defines its own worker count and duration, and stages run sequentially. Explicitly passing -w or -d overrides the stages section and falls back to single-stage mode. See Configuration > Stages for details.
edg run \
--driver pgx \
--config examples/stages/workload.edg \
--url "postgres://root@localhost:26257?sslmode=disable"
Error Handling#
Query errors during run are non-fatal. The worker logs the error and increments an error counter but continues to the next iteration. This lets you observe error rates without aborting the benchmark. Errors in other sections (up, seed, deseed, down, init) are fatal and stop execution immediately.
Interrupting with Ctrl+C#
Pressing Ctrl+C during run or all cancels the workload gracefully. Workers finish their current iteration and stop. When using all, the cleanup phase (down) still runs after interruption, using a fresh context.
Pausing before teardown#
all tears down what it created as soon as the run finishes, which leaves nothing to look at. --pause holds the process between the two:
edg all --config workload.edg --pauseTransactions: 18083
Errors: 0
tpm: 18082.3
paused before teardown: press enter or ctrl+c to run deseed and downQuery the database, then press enter or Ctrl+C to carry on. deseed and down run as usual afterwards, and they run from a fresh context, so interrupting to resume does not skip them.
The pause also ends when standard input does, so a pipeline that redirects stdin from /dev/null tears down immediately rather than hanging. A config with neither a deseed nor a down section never pauses - there is nothing to hold back. compare all takes the same flag, pausing once before both databases are torn down.
Under --tui there is no prompt: the TUI holds its final frame instead, with the clock frozen so the chart stays over the data. See the TUI’s keyboard shortcuts.
Output#
During the run, progress is printed at the --print-interval (default: every second):
59s / 1m0s
QUERY          COUNT  ERRORS  p90      p95      p99      QPS
check_balance  3674   0       3.584ms  4.154ms  6.252ms  62.3
credit_target  3769   0       2.261ms  2.624ms  3.911ms  63.9
debit_source   3769   0       3.214ms  3.722ms  5.288ms  63.9
read_source    3770   0       2.806ms  3.254ms  5.052ms  63.9
read_target    3769   0       3.871ms  4.486ms  6.446ms  63.9

TRANSACTION    COMMITS  ROLLBACKS  ERRORS  p90       p95       p99       TPS
make_transfer  3769     0          0       15.923ms  18.498ms  26.074ms  63.9
After all workers complete, a final summary is printed:
summary
Duration:  1m0.004s
Workers:   1

QUERY          COUNT  ERRORS  p90      p95      p99      QPS
check_balance  3749   0       3.571ms  4.14ms   6.249ms  62.5
credit_target  3828   0       2.261ms  2.624ms  3.911ms  63.8
debit_source   3828   1       3.216ms  3.724ms  5.338ms  63.8
read_source    3829   0       2.803ms  3.25ms   5.052ms  63.8
read_target    3829   0       3.868ms  4.485ms  6.446ms  63.8

TRANSACTION    COMMITS  ROLLBACKS  ERRORS  p90       p95       p99       TPS
make_transfer  3828     0          1       15.923ms  18.498ms  26.652ms  63.8

Transactions:  19063
Errors:        1
tpm: 19061.6| Metric | Description |
|---|---|
| COUNT | Total successful query executions |
| ERRORS | Total failed query executions |
| p90 | 90th percentile latency (sliding window) |
| p95 | 95th percentile latency (sliding window) |
| p99 | 99th percentile latency (sliding window) |
| QPS | Queries per second (count / elapsed seconds) |
| tpm | Transactions per minute across all queries |
Expectations#
When the config file includes an expectations section, results are printed after the summary and the exit code reflects whether all expectations passed:
expectations
  PASS  error_rate < 1
  PASS  check_balance.p99 < 100
  FAIL  tpm > 5000

1 expectation(s) failed
If any expectation fails, edg exits with status code 1. When using all, teardown (down) still runs before the non-zero exit.
See Configuration > Expectations for the full list of available metrics and expression syntax.
Formatting#
The fmt command applies canonical formatting to .edg config files. It preserves comments, normalizes indentation to 2 spaces, reorders top-level blocks into a canonical order, and leaves SQL inside backticks untouched.
# Print formatted output to stdout.
edg fmt workload.edg

# Format in-place.
edg fmt -w workload.edg

# Format multiple files.
edg fmt -w *.edg

# The global --config flag works too, for consistency with the other commands.
edg fmt --config workload.edg

# Read from stdin when no file is given.
cat workload.edg | edg fmt
Running fmt twice produces identical output (idempotent). The formatted file is semantically equivalent to the original, edg validate config will produce the same result before and after formatting.
Formatting rules#
| Rule | Detail |
|---|---|
| Indentation | 2 spaces per nesting level |
| Blank lines | Normalized to at most 1 between declarations |
| Comments | Preserved in place (# leading and trailing comments) |
| SQL | Content between backticks is never modified |
| Single argument | Kept inline: (expr) |
| Multiple arguments | One per line, indented, closing ) at the query’s indent level |
| Inline sections | Single-query sections that fit on one line are kept inline |
| Expressions | Operators are spaced, calls and indexes are not: a * (b + c), pow(x, 2), m['k'] |
| Block order | Top-level blocks are moved into canonical order (see below) |
Block order#
fmt moves top-level blocks into the order below, taking each block’s comments with it. Blocks of the same kind (and seq/signal/season, which share a slot) keep the order they were written in.
include, import and csv are pinned to the top, because the parser rejects them after any declaration.
include
import
csv
sim
let
expr
target
seq / signal / season
ref
object
tree
template
complete
workers
up
seed
stages
weights
init
run
stats
deseed
down
expect
Performance Testing#
The perf command contains tools for finding the performance limits of a database.
Breakpoint#
The perf breakpoint command finds the point where your database starts to degrade under load. It starts with 1 worker and adds another every --ramp-interval, monitoring latency, throughput, and errors and printing warnings whenever a percentage threshold is encountered (e.g. 50 meaning 50% more errors, 50% greater p99 latency or 50% fewer QPS). When an absolute --stop-p99, --stop-qps, or --stop-errors limit is hit, it stops and prints the summary.
edg perf breakpoint \
  --driver pgx \
  --config workload.edg \
  --url ${DATABASE_URL} \
  --ramp-interval 30s \
  --threshold 50 \
  --stop-p99 100ms
See Breakpoint Testing for flags, degradation warnings, stop conditions, and examples.
Drawing a Signal#
Not every load shape is worth deriving from sin, cos and mod. The signal draw command opens a bar editor in the terminal where you shape the curve a point at a time and export it as a signal definition. When the shape is maths, signal explore plots the expression instead.
edg signal draw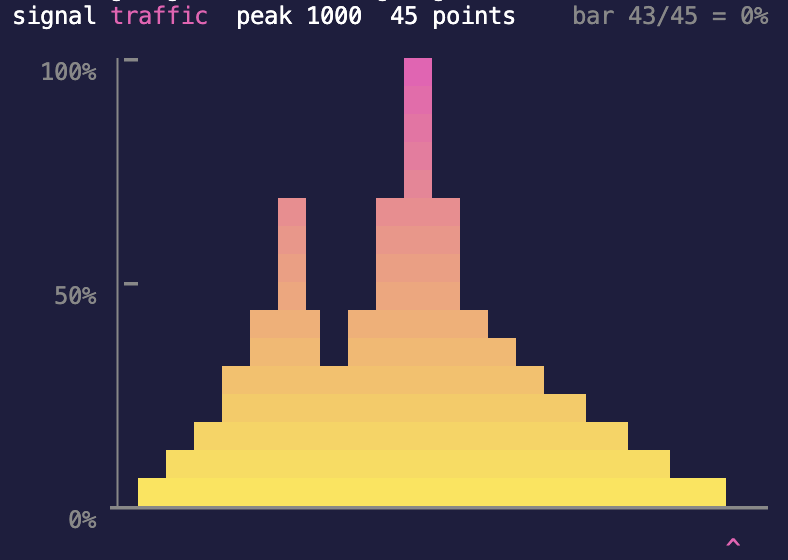
You start on a single bar. ↑/↓ set its height, → moves to the next bar and adds one when you’re already on the last, and ← goes back to edit what you’ve drawn. Bars are shaded yellow at the floor through to pink at the top, so height reads as colour as well as length, and the bar under the cursor is picked out in white. Nothing is written to disk and no database connection is needed.
You can also draw the shape with the mouse: hold the left button and drag across the chart. Each column follows the pointer, dragging past the right-hand end extends the curve, and a fast drag is joined up as a straight line rather than leaving the bars it skipped behind. The editor takes over the screen while it runs and hands it back on exit, so only the exported signal is left in your scrollback. Mouse reporting means your terminal’s own text selection is off while the editor is open - most terminals still select when you hold shift.
A keypress moves a bar half a row, which is the smallest step the chart can draw: a bar that stops on a half lands as ▄. The mouse draws to whole rows, so keys are the way to land between them.
| Flag | Default | Description |
|---|---|---|
--name | traffic | Name of the exported signal. |
--peak | 1000 | Value of the tallest bar. |
--decimals | 2 | Decimal places in the exported values. |
Keys and mouse#
| Input | Action |
|---|---|
↑ / ↓ | Raise or lower the bar under the cursor by half a row |
| Left-drag | Draw the curve under the pointer; dragging past the end extends it |
→ / ← | Move between bars; → on the last bar appends a new one at the same height |
d / backspace | Delete the bar under the cursor |
home / end | Jump to the first or last bar |
+ / - | Raise or lower the peak |
e / enter | Export to stdout and quit |
q / esc | Quit without exporting |
Values#
Bar heights are relative. The chart is drawn as a percentage of its own height, so the axis stays put while you draw. Values are applied on export: the tallest bar is worth --peak and every other bar keeps its ratio to it, so you shape the curve first and name its ceiling afterwards - pressing + rescales the whole curve rather than editing any one point. In the chart above the tallest bar is worth 1000, so a bar half its height is worth 500.
Output#
The bars are inlined as an array, so the exported signal reproduces exactly what was drawn. A signal whose body is a literal array needs no length: the parser counts the points and indexes them:
signal traffic {
  [125.00, 250.00, 437.50, 687.50, 875.00, 1000.00, 937.50, 750.00, 500.00, 312.50, 187.50, 125.00]
}
Export goes to stdout, so it can be redirected or piped straight into a config:
edg signal draw >> config.edgRead it like any other signal, with signal(), signal_at() or signal_correlated(), or point a stage’s qps at it to shape arrival rate. Output is already formatted the way edg fmt writes it, so pasting it in won’t cause a reformat.
Exploring a Signal#
A signal expression is maths you can’t see the result of until something runs it. The signal explore command plots it as you type, using the same line chart the TUI draws, so the curve on screen is the curve the run will follow.
edg signal exploreName a bundled shape to start from its expression rather than an empty line, which is the quickest way to take one of them and change it:
edg signal explore edg-business-hoursEvery keystroke re-evaluates the expression against the evaluator a run uses, so pow, cond, mod and signal_at() all behave here exactly as they will in a config, and the bundled shapes are available to build on without declaring anything. A half-typed expression doesn’t compile, so the chart holds the last curve that did and the error is printed under the input. Nothing is written to disk and no database connection is needed.
| Flag | Default | Description |
|---|---|---|
--name | traffic | Name of the exported signal. |
--length | 288 | Number of points to evaluate. |
--length is the length the exported block carries, and i runs from 0 to length - 1, so it is part of the shape rather than a view setting: an expression written against 288 points draws a different curve at 1440.
Keys#
| Input | Action |
|---|---|
enter | Export to stdout and quit |
esc | Clear the expression |
ctrl+c | Quit without exporting |
Export is refused while the expression is broken, because a config that doesn’t load isn’t worth writing.
Output#
The expression is exported as-is, with the length it was explored at:
signal traffic(length: 288) {
  0.15 + 0.85 * pow(sin(pi * i / 288.0), 2)
}
This is the same block edg signals --show prints, already formatted the way edg fmt writes it, so it can be redirected or piped straight into a config:
edg signal explore >> config.edgHoping this is abundantly obviously ↩︎